Agentic RAG · 2026–present
Agentic domain-specific RAG
A lab's literature of more than 10,000 papers, searchable by AI agents with every answer traced to the passage it came from.
The short version
Searching a lab's literature meant keyword matching that misses meaning, or an AI chatbot that invents its citations. Physics papers are hard to search: key results sit in figures, the argument runs through equations, and much of a sentence's meaning is in the reference it cites. The lab needed answers that trace to a specific passage in a specific paper.
Built in the Kläui Lab's AI and digitalization taskforce, which I lead, alongside the wiki search the same chatbot uses. Its verification approach comes from TracEx.
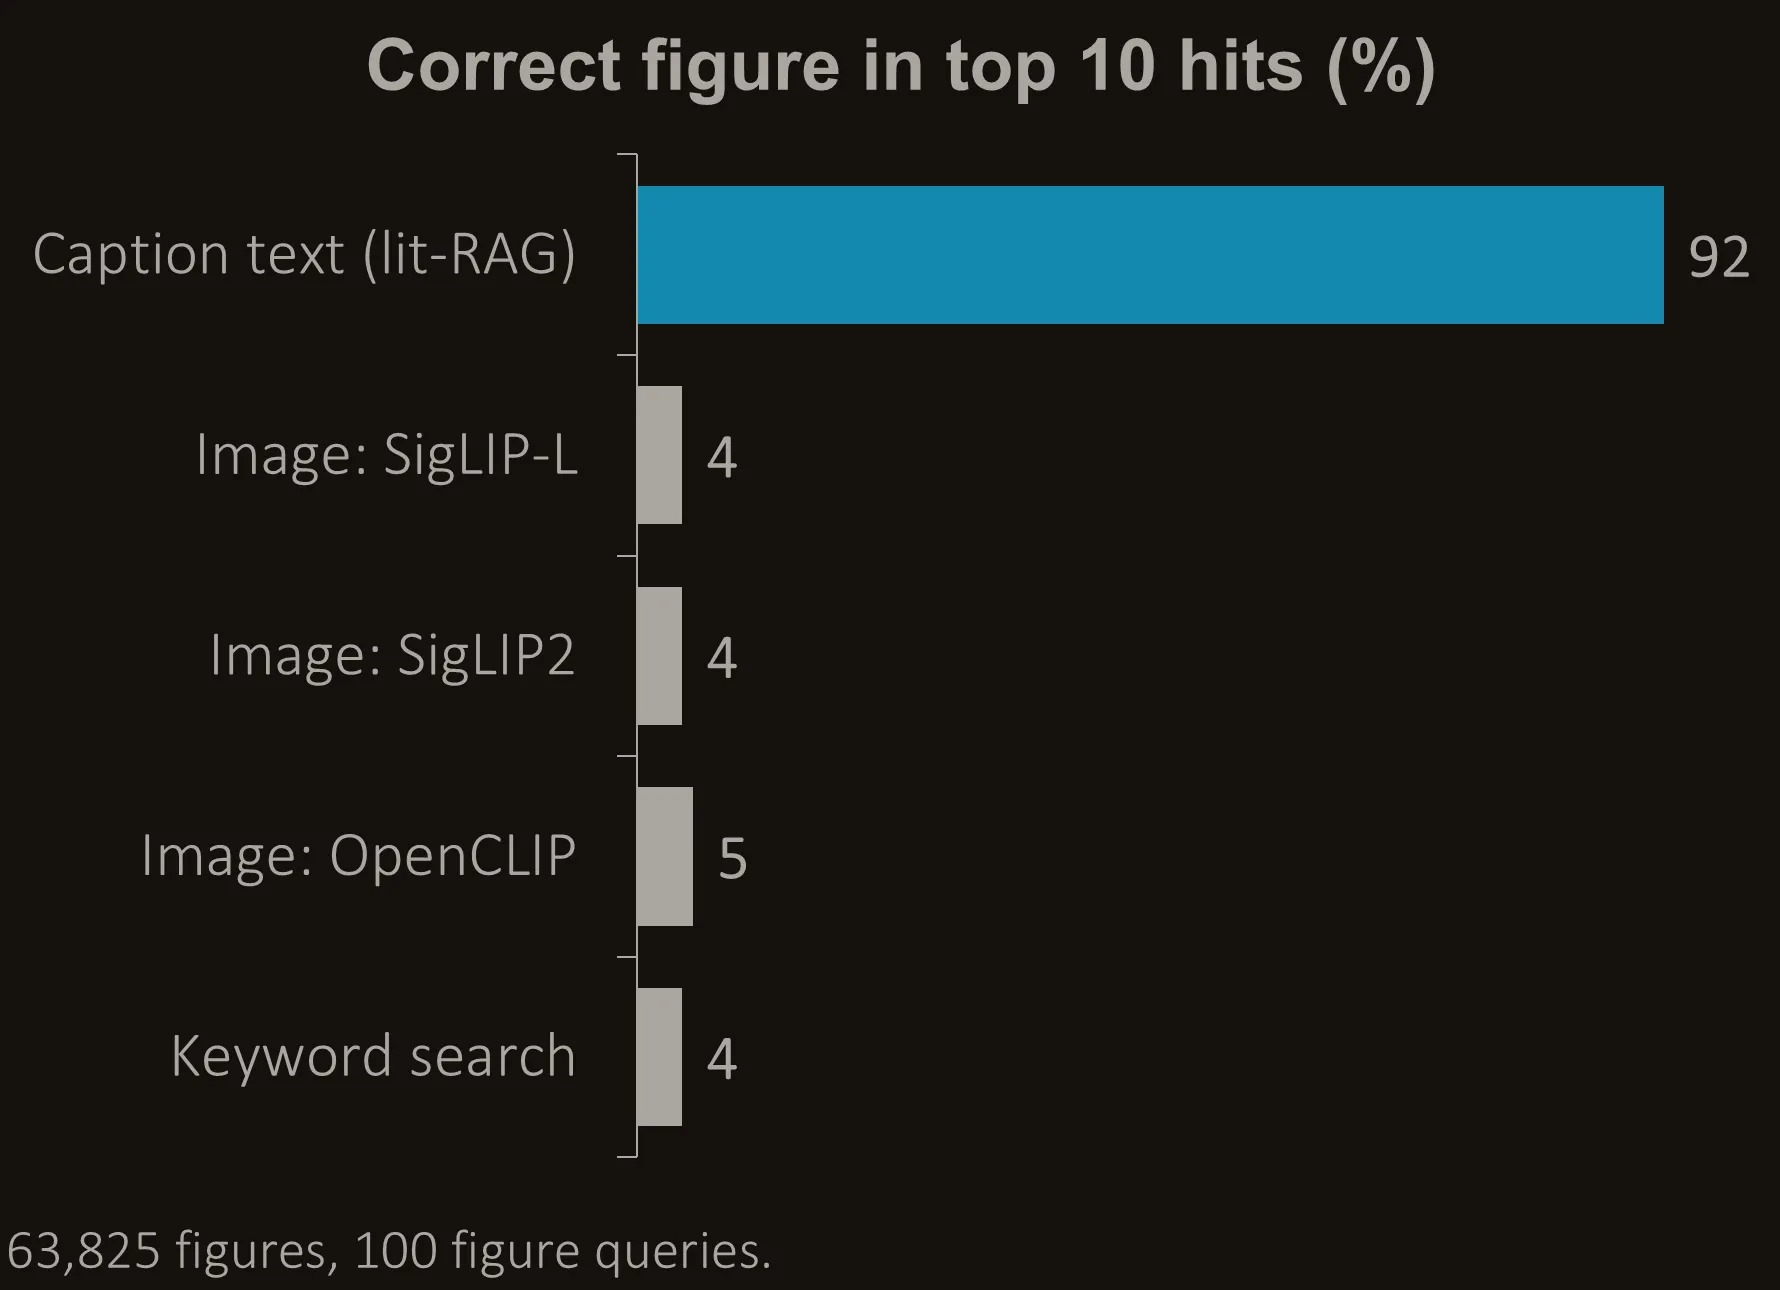 Searching caption text finds the right figure in the top 10 for 92% of questions; image embeddings manage 4 to 5%.
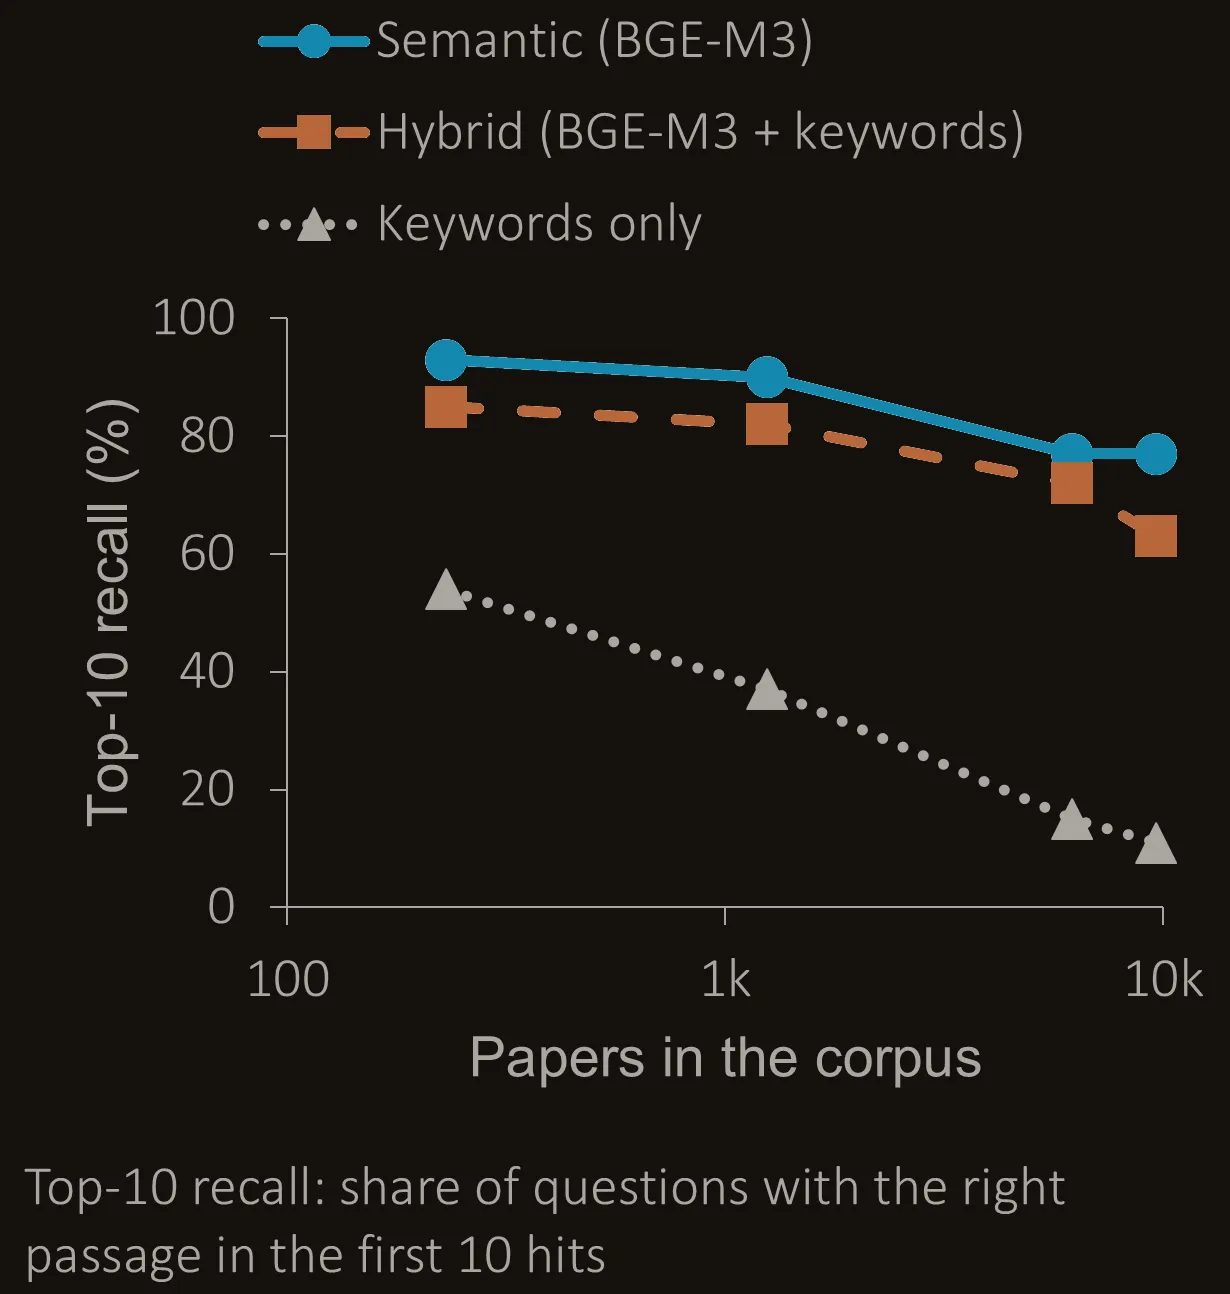 As the corpus grows to 10,000 papers, semantic search holds at 77% while keyword search collapses to 11%.
How
- Parsed every paper into a tree of blocks with Docling, GROBID and CrossRef: sections, paragraphs, figures with captions, equations and references, each with its page position. Every passage stores its source hash, embedding checkpoint and parser version, so an answer traces to the exact file and pipeline run.
- Built an agentic retriever. An AI agent runs semantic search over passages of about 500 tokens, embedded with BGE-M3 in PostgreSQL with pgvector, then follows the citations in what it found or walks the citation graph around a paper.
- Indexed figures by their caption text, with no pixels embedded and no vision model, which is what beat the image embeddings above.
- Dropped the standard hybrid recipe when the evaluation said so. Keyword Recall@10 fell from 0.54 to 0.11 as the corpus grew from 230 to 9,642 papers, and across 13 configurations the gain from fusing keywords into semantic search turned negative. PostgreSQL full-text search now only filters. Both gold sets were generated and adversarially verified, with no hand labelling.
- Served it as an MCP server with six tools (
search,get_paper,follow_citation,graph_walk,get_figures,report_issue) that return abstention as structured data. CI runs the check suite on every push, and a pinned retrieval baseline fails the build on a regression.
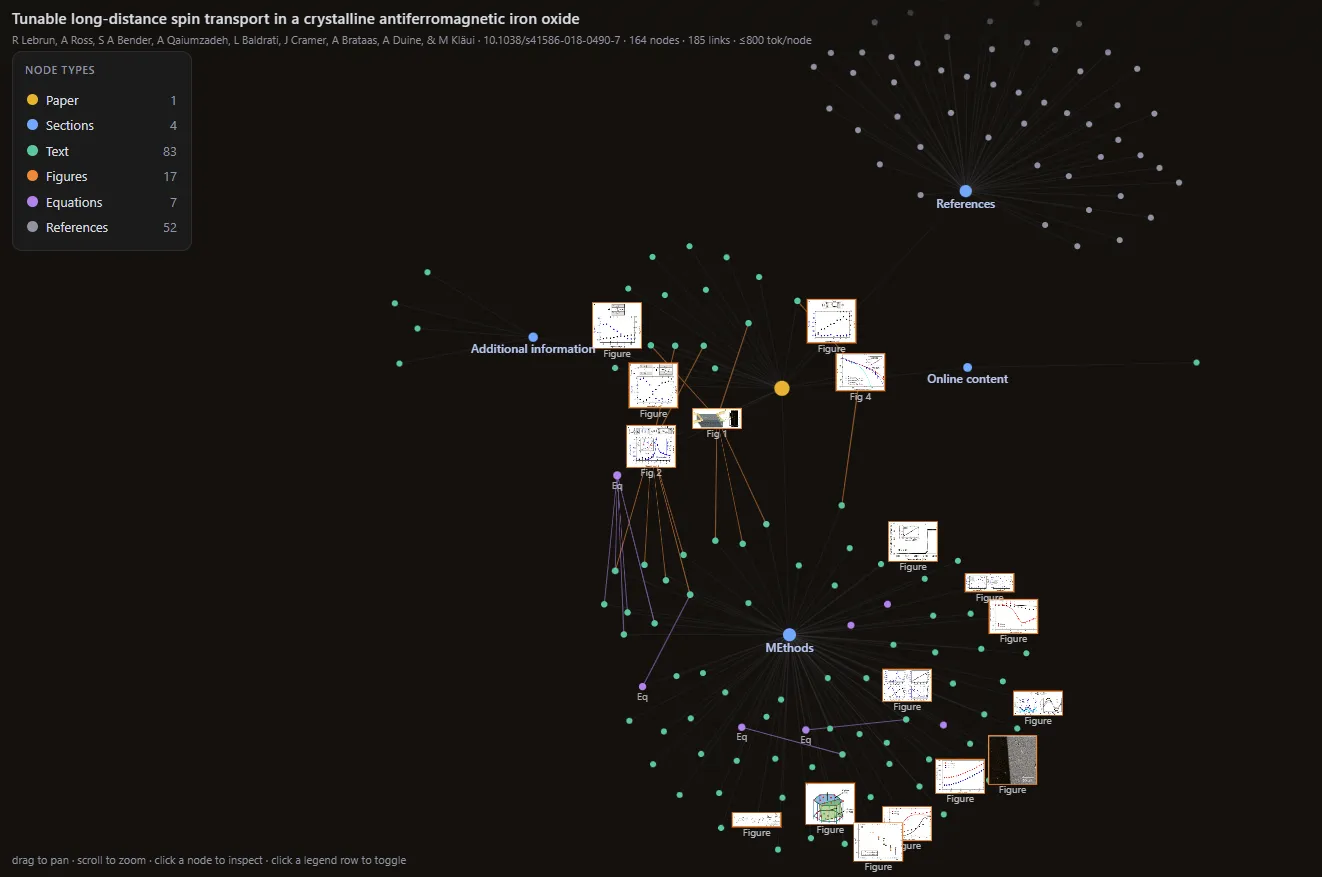 One paper as the parser sees it: 164 nodes and 185 links, with every figure tied to the text that cites it.
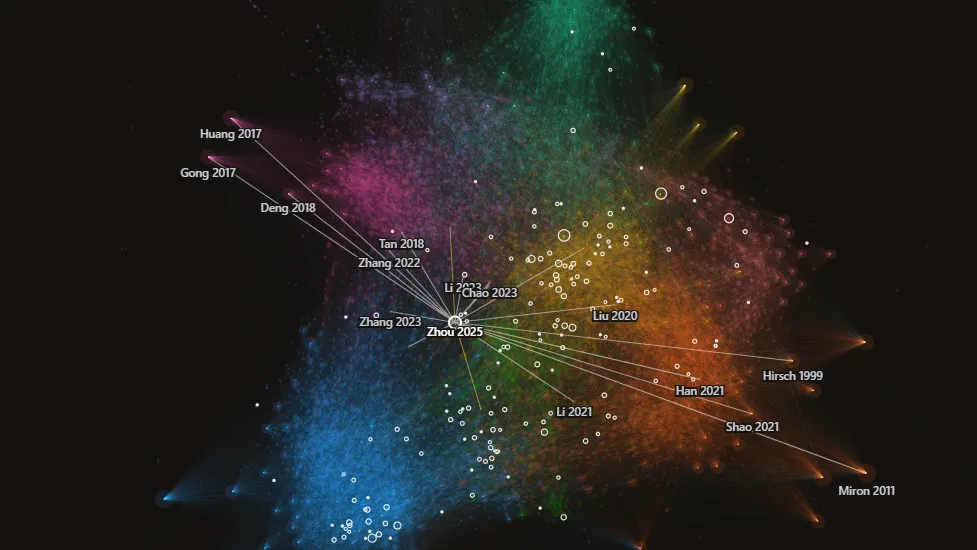
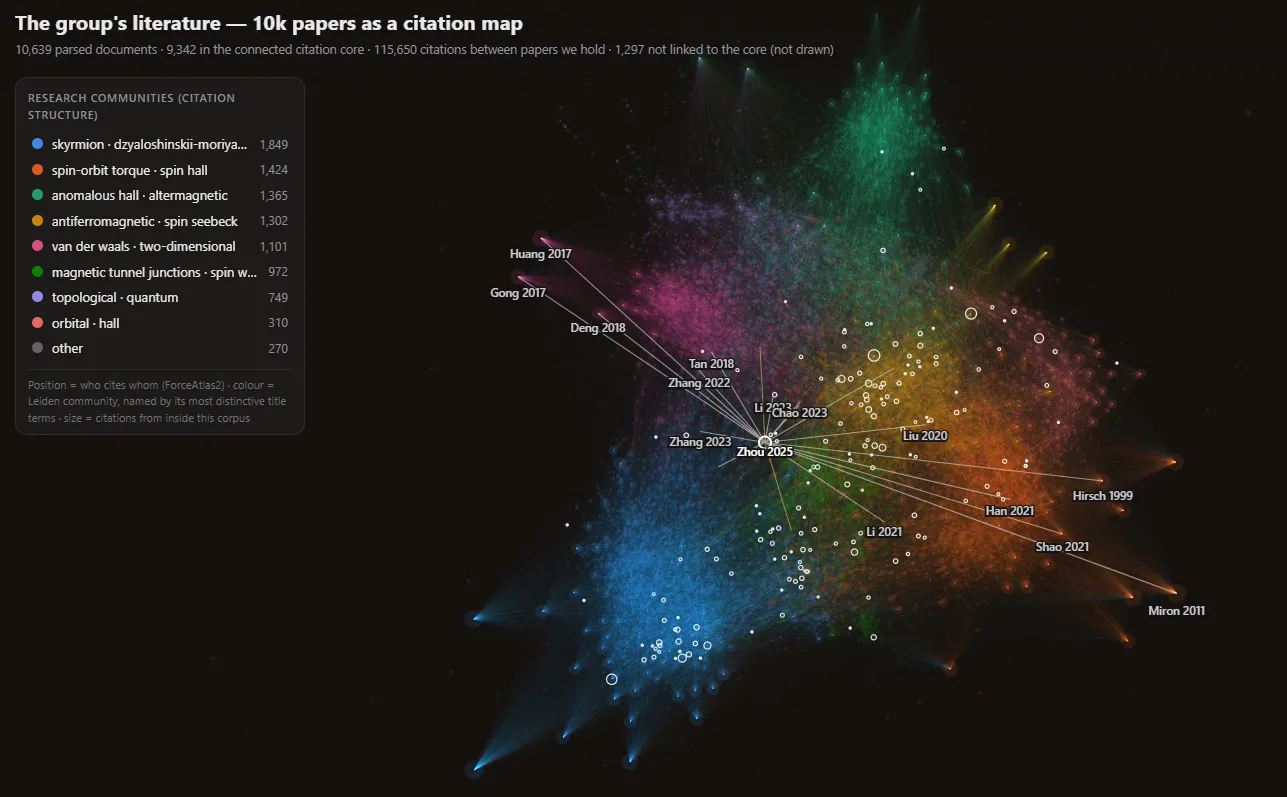 The citation graph the agent walks: position from who cites whom, colour from the research communities it contains.
In production alongside retrieval over the group's internal wiki. An agent that works through the literature on its own over a longer task is not built. I presented the results at AI4Sci 2026; the code is not public yet.